Local LLM Hardware Index: November 17, 2026
A weekly, automatically generated snapshot of how much memory popular open AI models need and what hardware runs them. Edition 2026-11-17, built from data fetched 2026-11-17 23:34 UTC. Permanent link to this edition: https://runsonmy.com/report/2026-11-17/.
Key findings
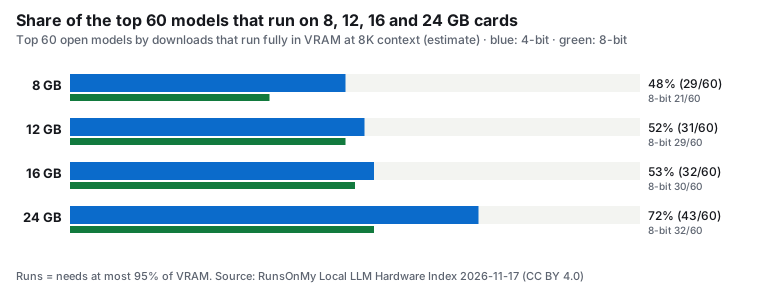
- 29 of the 60 most-downloaded open models we track (48%) run fully on an 8 GB card at 4-bit with 8K context. Doubling to 16 GB adds only 3 more (32/60); 24 GB reaches 43/60 (72%).
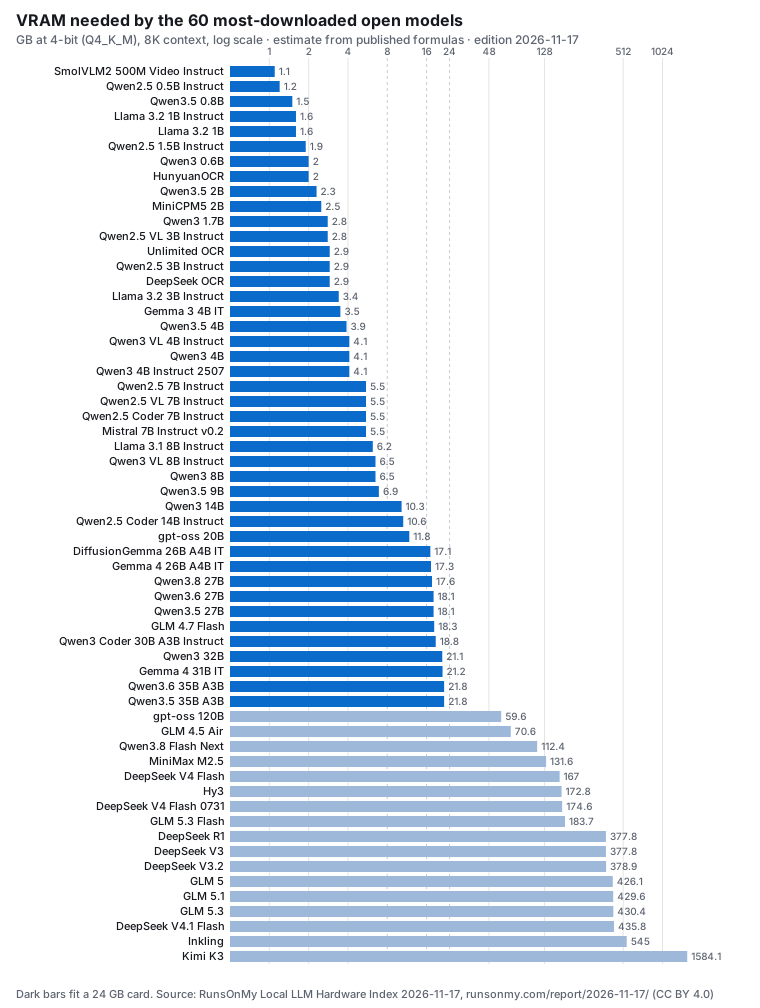
- The median top-60 model needs about 10.5 GB at 4-bit. The middle half ranges from 3.4 to 112.4 GB, and 17 need more than 48 GB, beyond any single consumer card.
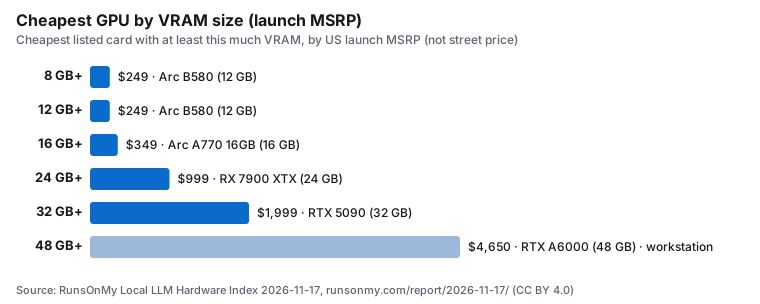
- The cheapest card we list with at least 8 GB is the Arc B580 (12 GB) at a $249 launch MSRP, cheaper than any 8 GB card we list. The cheapest 24 GB card is the RX 7900 XTX at $999. Launch prices, not today's street prices.
- 2 newly released models joined the tracked set this week: SenseNova Loop 9B (6.4 GB), KORMo Web 11B (8.3 GB).
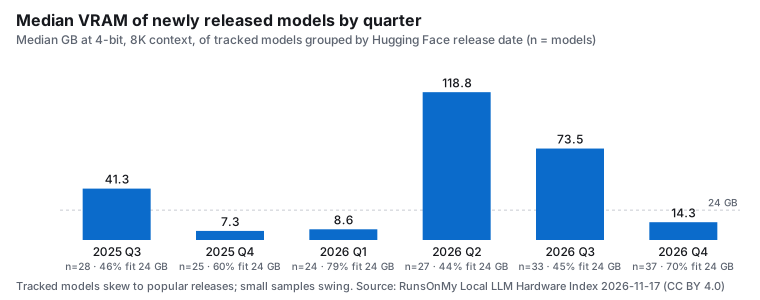
- Release trend: the median tracked model released in 2026 Q4 needs 14.3 GB at 4-bit (n=37), versus 73.5 GB in 2026 Q3 (n=33); 70% of 2026 Q4 releases fit 24 GB versus 45%. Over the last 4 quarters the median has gone up and down (8.6, 118.8, 73.5, 14.3 GB), so there is no steady trend either way.
How much VRAM the top 60 models need
Share of popular models that run on 8, 12, 16 and 24 GB
Cheapest GPU per VRAM tier
SVG · 32 consumer cards with a known launch MSRP. Macs are not included because our table has no Mac prices.
This week vs last week
This is the first edition. Whole-catalog metrics as of the previous week, reconstructed by removing models released in the last 7 days. Download ranks for last week are not available, so top-60 metrics start week-over-week with the next edition.
| Metric | This week | Last week (reconstructed) | Change |
|---|---|---|---|
| Open models tracked | 298 | 296 | +2 |
| Median VRAM, all tracked (GB, 4-bit) | 8.8 | 9.5 | −0.7 |
| All tracked models that run on 8 GB | 142 | 141 | +1 |
| All tracked models that run on 12 GB | 162 | 160 | +2 |
| All tracked models that run on 16 GB | 168 | 166 | +2 |
| All tracked models that run on 24 GB | 204 | 202 | +2 |
New models this week
| Model | Released | Params | VRAM at 4-bit (est.) | Smallest tier |
|---|---|---|---|---|
| SenseNova Loop 9B sensenova | 2026-11-17 | 9.4B | 6.4 GB | 8 GB |
| KORMo Web 11B KORMo-VL | 2026-11-14 | 11B | 8.3 GB | 12 GB |
VRAM by release quarter
The top 60 models
| # | Model | Params | 4-bit GB (est.) | 8-bit GB (est.) | Smallest tier |
|---|---|---|---|---|---|
| 1 | Qwen3 0.6B | 752M | 2 | 2.3 | 8 GB |
| 2 | Qwen3 14B | 15B | 10.3 | 16.6 | 12 GB |
| 3 | DeepSeek V3.2 MoE | 685B | 378.9 | 665.6 | >48 GB |
| 4 | Qwen3.8 27B | 28B | 17.6 | 28.5 | 24 GB |
| 5 | Qwen3 VL 8B Instruct | 8.8B | 6.5 | 9.9 | 8 GB |
| 6 | Qwen2.5 7B Instruct | 7.6B | 5.5 | 8.7 | 8 GB |
| 7 | GLM 5.3 Flash MoE | 321B | 183.7 | 318.4 | >48 GB |
| 8 | Gemma 4 31B IT | 31B | 21.2 | 33.3 | 24 GB |
| 9 | Qwen3.5 9B | 9.7B | 6.9 | 10.3 | 8 GB |
| 10 | Qwen3 8B | 8.2B | 6.5 | 9.9 | 8 GB |
| 11 | Unlimited OCR MoE | 3.3B | 2.9 | 4 | 8 GB |
| 12 | gpt-oss 20B MoE | 21B | 11.8 | 12.3 | 16 GB |
| 13 | Qwen3.5 2B | 2.3B | 2.3 | 2.9 | 8 GB |
| 14 | Qwen2.5 VL 7B Instruct | 8.3B | 5.5 | 8.7 | 8 GB |
| 15 | Gemma 4 26B A4B IT MoE | 26B | 17.3 | 26.4 | 24 GB |
| 16 | Qwen2.5 1.5B Instruct | 1.5B | 1.9 | 2.7 | 8 GB |
| 17 | Qwen3.5 4B | 4.7B | 3.9 | 5.4 | 8 GB |
| 18 | Llama 3.1 8B Instruct | 8.0B | 6.2 | 9.6 | 8 GB |
| 19 | Qwen2.5 0.5B Instruct | 494M | 1.2 | 1.4 | 8 GB |
| 20 | Qwen3.6 35B A3B MoE | 36B | 21.8 | 36.2 | 24 GB |
| 21 | Qwen3 32B | 33B | 21.1 | 35.1 | 24 GB |
| 22 | Qwen3 VL 4B Instruct | 4.4B | 4.1 | 5.8 | 8 GB |
| 23 | Qwen3 4B | 4.0B | 4.1 | 5.8 | 8 GB |
| 24 | Qwen3.8 Flash Next MoE | 180B | 112.4 | 176.4 | >48 GB |
| 25 | Qwen3.5 0.8B | 873M | 1.5 | 1.7 | 8 GB |
| 26 | Qwen3 1.7B | 2.0B | 2.8 | 3.6 | 8 GB |
| 27 | Qwen3 4B Instruct 2507 | 4.0B | 4.1 | 5.8 | 8 GB |
| 28 | Qwen3.6 27B | 28B | 18.1 | 28.5 | 24 GB |
| 29 | gpt-oss 120B MoE | 117B | 59.6 | 60.1 | >48 GB |
| 30 | DeepSeek V4 Flash 0731 MoE | 304B | 174.6 | 302.4 | >48 GB |
| 31 | Qwen3 Coder 30B A3B Instruct MoE | 31B | 18.8 | 31.7 | 24 GB |
| 32 | Qwen2.5 3B Instruct | 3.1B | 2.9 | 4.3 | 8 GB |
| 33 | Qwen2.5 VL 3B Instruct | 3.8B | 2.8 | 4 | 8 GB |
| 34 | DeepSeek OCR MoE | 3.3B | 2.9 | 4 | 8 GB |
| 35 | GLM 5.3 MoE | 753B | 430.4 | 747.9 | >48 GB |
| 36 | SmolVLM2 500M Video Instruct | 507M | 1.1 | 1.2 | 8 GB |
| 37 | Qwen3.5 27B | 28B | 18.1 | 28.5 | 24 GB |
| 38 | Qwen2.5 Coder 14B Instruct | 15B | 10.6 | 16.8 | 12 GB |
| 39 | DeepSeek R1 MoE | 684B | 377.8 | 665.5 | >48 GB |
| 40 | DeepSeek V4.1 Flash MoE | 763B | 435.8 | 756.6 | >48 GB |
| 41 | Qwen2.5 Coder 7B Instruct | 7.6B | 5.5 | 8.7 | 8 GB |
| 42 | Inkling MoE | 952B | 545 | 800.8 | >48 GB |
| 43 | Qwen3.5 35B A3B MoE | 36B | 21.8 | 36.2 | 24 GB |
| 44 | DeepSeek V3 MoE | 684B | 377.8 | 665.5 | >48 GB |
| 45 | Llama 3.2 1B Instruct | 1.2B | 1.6 | 2.1 | 8 GB |
| 46 | DeepSeek V4 Flash MoE | 291B | 167 | 289.3 | >48 GB |
| 47 | GLM 5 MoE | 754B | 426.1 | 747.8 | >48 GB |
| 48 | GLM 4.7 Flash MoE | 31B | 18.3 | 30.8 | 24 GB |
| 49 | Mistral 7B Instruct v0.2 | 7.2B | 5.5 | 8.6 | 8 GB |
| 50 | GLM 4.5 Air MoE | 110B | 70.6 | 111.5 | >48 GB |
| 51 | MiniMax M2.5 MoE | 229B | 131.6 | 229.2 | >48 GB |
| 52 | Gemma 3 4B IT | 4.3B | 3.5 | 5 | 8 GB |
| 53 | Hy3 MoE | 299B | 172.8 | 299 | >48 GB |
| 54 | MiniCPM5 2B | 2.5B | 2.5 | 3.5 | 8 GB |
| 55 | Llama 3.2 3B Instruct | 3.2B | 3.4 | 4.7 | 8 GB |
| 56 | Kimi K3 MoE | 2.78T | 1584.1 | 2752.4 | >48 GB |
| 57 | GLM 5.1 MoE | 754B | 429.6 | 747.8 | >48 GB |
| 58 | Llama 3.2 1B | 1.2B | 1.6 | 2.1 | 8 GB |
| 59 | DiffusionGemma 26B A4B IT MoE | 26B | 17.1 | 26.4 | 24 GB |
| 60 | HunyuanOCR | 1.1B | 2 | 2.5 | 8 GB |
Method and caveats
- Models: Top 60 tracked open models by Hugging Face downloads (last 30 days), from the 298 open models RunsOnMy tracks. Download counts are Hugging Face's rolling 30-day figures.
- VRAM figures are estimates from the published formulas: weights (real GGUF file sizes where available), KV cache for the model's attention design at 8K context, and runtime overhead. Not measured on hardware.
- "Runs on N GB": the model needs at most 95% of the card's VRAM (fits or tight), same rule as the rest of the site. CPU offload is not counted.
- Prices: US launch MSRP, not current street price.
- Release trend: grouped by Hugging Face creation date of models we track. The tracked set favours popular releases, so it is not a census of all models.
- Each edition is frozen when published. Errors: corrections.
Cite this
RunsOnMy (2026). Local LLM Hardware Index, edition 2026-11-17. https://runsonmy.com/report/2026-11-17/. Data CC BY 4.0.
BibTeX
@misc{runsonmy_index_20261117,
  title  = {Local LLM Hardware Index, edition 2026-11-17},
  author = {{RunsOnMy}},
  year   = {2026},
  url    = {https://runsonmy.com/report/2026-11-17/},
  note   = {Automated weekly snapshot; data CC BY 4.0}
}
Permalink: https://runsonmy.com/report/2026-11-17/ · Data: top60.csv, tiers.csv · Charts (SVG): vram-top60, cheapest-gpu, share-runnable, release-trend · License: CC BY 4.0 (credit "RunsOnMy" with a link).
All editions
- November 17, 2026 (this edition)